Potato Leaf Disease Prediction
The Potato Disease Classification System is an AI-powered deep learning project designed to automatically identify the health condition of potato leaves from images. The system uses computer vision and transfer learning to classify potato leaves into three categories: Early Blight, Late Blight, and Healthy.
The project uses EfficientNetB0, a pretrained convolutional neural network, as its primary model architecture. Through transfer learning and fine-tuning, the model learns important visual patterns from potato leaf images and uses these features to make accurate disease predictions.
The final model achieved 98.15% test accuracy, correctly classifying 212 out of 216 test images. It achieved particularly strong performance in identifying Early Blight and Healthy leaves, while the small number of errors was mainly associated with confusion between Early Blight and Late Blight.
EfficientNetB0
Transfer Learning
Fine-Tuning
Deep Learning
98.2%
Test Accuracy
97.03%
Macro F1-Score
98%
Avg. Confidence
The primary model used in this project is EfficientNetB0, a convolutional neural network architecture pretrained on the ImageNet dataset. EfficientNetB0 is designed to achieve a strong balance between model accuracy and computational efficiency, making it suitable for image classification applications.
For this project, the original ImageNet classification layer was removed and replaced with a custom classification head specifically designed for potato leaf disease detection.
The project uses Transfer Learning to take advantage of visual features already learned by EfficientNetB0 from the large ImageNet dataset. During the first training stage, the pretrained EfficientNetB0 backbone is frozen while the new potato-disease classification layers are trained.
This approach allows the model to learn effectively from the available potato leaf images without requiring the entire network to be trained from the beginning.
Potato Leaf Disease Prediction
The Insurance Cost Prediction System is a machine learning regression application designed to predict insurance costs using customer-related and health-related attributes. The project follows a complete machine learning workflow, including data preprocessing, exploratory data analysis, feature engineering, model training, hyperparameter optimization, cross-validation, and model evaluation.
Multiple regression algorithms are trained and compared to identify the most effective model for predicting insurance costs. The selected model can be integrated into an interactive application to provide real-time insurance cost predictions.
The project demonstrates how machine learning can be applied to insurance analytics to support data-driven cost estimation and predictive decision-making.
EfficientNetB0
Transfer Learning
Fine-Tuning
Deep Learning
98.15%
Test Accuracy
97.03%
Macro F1-Score
97.98%
Avg. Confidence
The primary model used in this project is EfficientNetB0, a convolutional neural network architecture pretrained on the ImageNet dataset. EfficientNetB0 is designed to achieve a strong balance between model accuracy and computational efficiency, making it suitable for image classification applications.
For this project, the original ImageNet classification layer was removed and replaced with a custom classification head specifically designed for potato leaf disease detection.
The project uses Transfer Learning to take advantage of visual features already learned by EfficientNetB0 from the large ImageNet dataset. During the first training stage, the pretrained EfficientNetB0 backbone is frozen while the new potato-disease classification layers are trained.
This approach allows the model to learn effectively from the available potato leaf images without requiring the entire network to be trained from the beginning.
Project Description
The Potato Disease Detection System is an AI-powered image classification application developed to identify potato leaf conditions from images. The system uses deep learning and computer vision techniques to classify potato leaves into three categories: Early Blight, Late Blight, and Healthy.
The project demonstrates an end-to-end machine learning workflow, including image dataset validation, image quality auditing, duplicate detection, stratified dataset splitting, preprocessing, data augmentation, class imbalance handling, transfer learning, model fine-tuning, performance evaluation, and production model deployment.
The system processes input leaf images at 224 × 224 RGB resolution and uses a pretrained EfficientNetB0 architecture to extract visual features and classify the disease condition. Through transfer learning and fine-tuning, the model learns disease-specific visual patterns while leveraging knowledge learned from the ImageNet dataset.
The project is designed for educational, research, and analytical purposes and demonstrates how deep learning can be applied to automated plant disease classification.
Problem Statement
Potato crops are vulnerable to diseases that can significantly affect plant health and agricultural productivity. Early Blight and Late Blight are two important potato leaf diseases that can produce visually similar symptoms, making manual identification difficult in some cases.
Traditional disease identification often depends on visual inspection and expert knowledge. This can be time-consuming and may lead to inconsistent results, especially when large numbers of plants need to be examined.
This project addresses the problem by developing an automated image-based classification system capable of analyzing potato leaf images and identifying whether the leaf belongs to the Early Blight, Late Blight, or Healthy category.
The system provides a machine-learning-based approach for rapid classification while maintaining strong predictive performance on previously unseen test images.
Objectives
The primary objectives of this project are:
- Develop an automated potato leaf disease classification system using deep learning.
- Classify potato leaf images into Early Blight, Late Blight, and Healthy categories.
- Build a reliable image preprocessing and dataset validation pipeline.
- Apply image augmentation to improve model generalization.
- Handle class imbalance using balanced class weights.
- Use transfer learning with a pretrained EfficientNetB0 architecture.
- Fine-tune selected layers of the pretrained network for potato disease classification.
- Evaluate the model using accuracy, precision, recall, F1-score, loss, and confusion matrix analysis.
- Analyze class-wise performance and prediction confidence.
- Save the trained model and supporting metadata for production use.
- Demonstrate an end-to-end deep learning workflow suitable for an interactive prediction application.
AI-Powered Potato Disease Detection
The Potato Disease Detection System uses advanced deep learning techniques to automatically analyze potato leaf images and predict their health condition.
The model classifies images into three categories:
- Early Blight
- Late Blight
- Healthy
The system processes an uploaded image and generates a predicted class along with prediction confidence.
Intelligent Image Processing
Before training, the dataset goes through a structured image-processing pipeline.
The system performs:
- Image file validation
- Corrupted-image detection
- Image dimension verification
- Color-mode validation
- Image resizing to 224 × 224 pixels
- RGB image processing
- TensorFlow dataset creation
- Batch validation
- Training, validation, and test dataset verification
This preprocessing pipeline helps maintain consistent input quality for the deep learning model.
Dataset Quality & Duplicate Analysis
The project includes dedicated dataset quality-control procedures before model training.
The pipeline checks:
- Invalid or unreadable images
- Images below the minimum required dimensions
- Unsupported image formats
- Exact duplicate files
- Near-duplicate images
- Class distribution
- Dataset split integrity
- Possible data leakage between training, validation, and test sets
These checks help improve the reliability of the training dataset.
Data Augmentation
The training pipeline applies image augmentation to increase the diversity of training samples.
Augmentation helps the model become more robust to variations in leaf images and reduces the risk of overfitting.
The augmented training pipeline is applied only to the training dataset while validation and test data remain suitable for unbiased evaluation.
Transfer Learning with EfficientNetB0
The project uses EfficientNetB0 as the primary deep learning architecture.
The pretrained backbone initially remains frozen while a new classification head is trained. After the first training stage, selected upper layers of EfficientNetB0 are unfrozen for fine-tuning.
The final model uses:
- EfficientNetB0 architecture
- Transfer learning
- Fine-tuning
- 224 × 224 × 3 input images
- 3-class classification output
- Sparse categorical cross-entropy loss
- Class weighting
- Adaptive learning-rate reduction
- Early stopping
- Model checkpointing
Performance Evaluation
The model is evaluated using multiple classification metrics rather than relying only on accuracy.
Evaluation includes:
- Accuracy
- Precision
- Recall
- F1-score
- Test loss
- Confusion matrix
- Class-wise performance
- Error rate
- Prediction confidence
- Correct vs. incorrect prediction analysis
These measurements provide a more complete understanding of the model’s classification performance.
Model Performance
The final EfficientNetB0 model achieved strong performance on the completely unseen test dataset.
Final Test Results
| Metric | Result |
|---|---|
| Test Samples | 216 |
| Correct Predictions | 212 |
| Incorrect Predictions | 4 |
| Test Accuracy | 98.15% |
| Test Loss | 0.0324 |
| Macro Precision | 95.64% |
| Macro Recall | 98.67% |
| Macro F1-Score | 97.03% |
| Weighted F1-Score | 98.16% |
| Test Error Rate | 1.85% |
| Average Test Confidence | 97.98% |
Class-Wise Performance
| Class | Test Samples | Correct Predictions | Incorrect Predictions | Accuracy | Precision | Recall | F1-Score |
|---|---|---|---|---|---|---|---|
| Early Blight | 100 | 100 | 0 | 100% | 98.04% | 100% | 99.01% |
| Late Blight | 100 | 96 | 4 | 96% | 100% | 96% | 97.96% |
| Healthy | 16 | 16 | 0 | 100% | 88.89% | 100% | 94.12% |
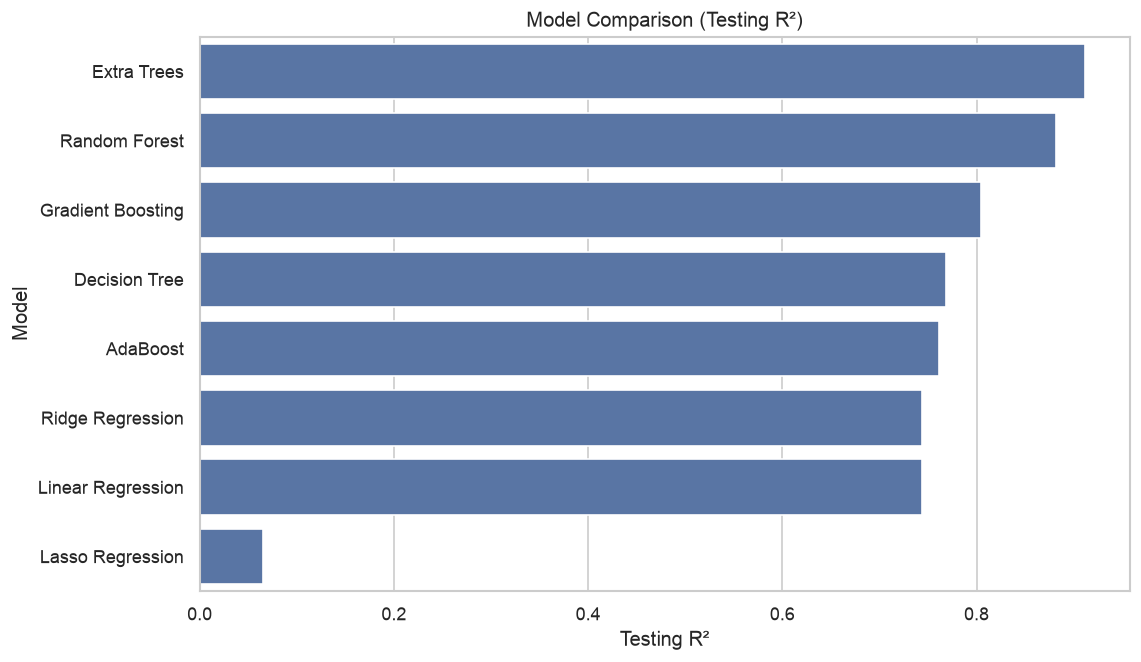
Model Comparision
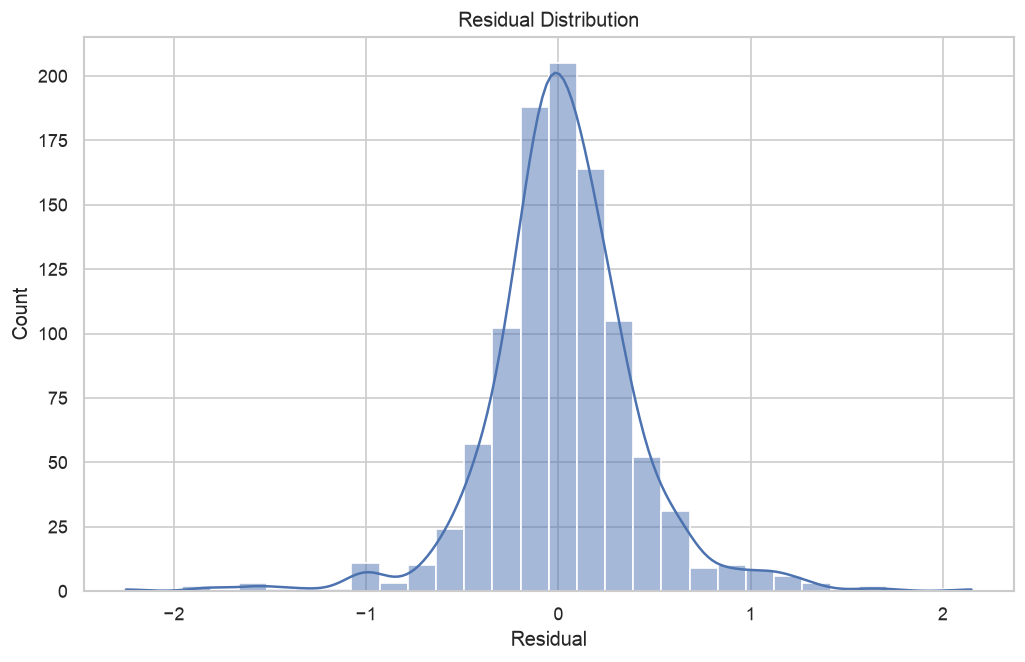
Distribution
Error Analysis
The final test evaluation produced only 4 incorrect predictions out of 216 images, resulting in an overall error rate of 1.85%.
All four errors occurred within the Late Blight class.
The most common confusion was:
Actual: Late Blight
Predicted: Early Blight
Occurrences: 2
This indicates that Early Blight and Late Blight can contain visually similar patterns that occasionally cause classification confusion.
The average confidence for correct predictions was approximately 98.70%, while the average confidence for incorrect predictions was approximately 59.95%.
Overall, the results demonstrate strong classification performance and good generalization on unseen test images.
1. Introduction
The Potato Disease Classification System is a deep-learning-based computer vision project designed to automatically identify potato leaf conditions from images.
The system classifies images into three categories:
- Early Blight
- Late Blight
- Healthy
The project follows a complete machine learning workflow, beginning with dataset discovery and quality auditing and continuing through preprocessing, augmentation, model training, fine-tuning, evaluation, error analysis, and production model serialization.
The final system uses EfficientNetB0 with transfer learning and fine-tuning and achieved 98.15% test accuracy on 216 unseen test images.
2. Objectives
The main objectives of the project are:
- Classify potato leaf images using deep learning.
- Detect Early Blight and Late Blight conditions.
- Identify healthy potato leaves.
- Build a reliable image preprocessing pipeline.
- Perform dataset quality and duplicate analysis.
- Apply data augmentation.
- Handle class imbalance.
- Use transfer learning for efficient model training.
- Fine-tune the pretrained model for improved performance.
- Evaluate the model using multiple classification metrics.
- Analyze classification errors and prediction confidence.
- Save the final model for deployment and future predictions.
3. System Overview
The complete workflow consists of:
Dataset Collection → Dataset Validation → Image Quality Audit → Duplicate Detection → Dataset Manifest → Stratified Train/Validation/Test Split → Split Verification → Image Preprocessing → Data Augmentation → Class Imbalance Handling → EfficientNetB0 Transfer Learning → First-Stage Training → Fine-Tuning → Training Analysis → Test Evaluation → Error Analysis → Model Selection → Production Model Saving
This workflow ensures that the model is trained and evaluated using a structured and reproducible process.
4. Technologies Used
| Category | Technology |
|---|---|
| Programming Language | Python |
| Deep Learning Framework | TensorFlow / Keras |
| Model Architecture | EfficientNetB0 |
| Data Processing | NumPy, Pandas |
| Image Processing | Pillow |
| Machine Learning Utilities | Scikit-learn |
| Visualization | Matplotlib |
| Image Hashing | ImageHash |
| Development Environment | Jupyter Notebook |
| Model Format | Keras (.keras) |
| Deployment | Streamlit |
5. Dataset
The project uses a potato leaf image dataset organized into three classes:
- Potato___Early_blight
- Potato___Late_blight
- Potato___healthy
The final test set contains 216 images:
| Class | Test Samples |
| Early Blight | 100 |
| Late Blight | 100 |
| Healthy | 16 |
| Total | 216 |
Images are processed as RGB images with an input resolution of 224 × 224 × 3.
6. Machine Learning Model
The primary model used in the project is EfficientNetB0.
The model uses transfer learning, starting from a pretrained EfficientNetB0 network and adapting it to the three potato leaf classes.
The training process consists of two stages:
Stage 1 — Transfer Learning
The pretrained EfficientNetB0 feature-extraction layers are frozen while a new classification head is trained for the potato disease classes.
Stage 2 — Fine-Tuning
The upper layers of the EfficientNetB0 backbone are partially unfrozen and trained using a smaller learning rate.
During fine-tuning:
- 30 backbone layers were trainable.
- 208 backbone layers remained frozen.
- Batch Normalization layers were kept frozen.
- A learning rate of 1e-5 was used initially.
- Early stopping and learning-rate reduction were applied.
The final model contains approximately 4.38 million parameters.
7. Data Preprocessing
Every image passes through a preprocessing pipeline before being supplied to the model.
The pipeline includes:
- Image loading
- Image validation
- RGB conversion
- Resizing to 224 × 224
- Tensor conversion
- Batch creation
- Dataset performance optimization
The test and validation datasets are kept separate from the augmented training pipeline to ensure unbiased evaluation.
8. Data Augmentation
Training images are augmented to provide additional visual variation.
This helps the model learn more robust image features and improves its ability to generalize to images that differ from the original training samples.
Augmentation is applied only to training data and is not used to artificially modify validation or test results.
9. Evaluation Metrics
The model is evaluated using:
- Accuracy — Overall percentage of correctly classified images.
- Precision — Measures how many predictions for a class are actually correct.
- Recall — Measures how many actual samples of a class are correctly identified.
- F1-Score — Harmonic mean of precision and recall.
- Loss — Measures the model’s classification error during evaluation.
- Confusion Matrix — Shows correct and incorrect predictions between classes.
- Error Rate — Percentage of test samples classified incorrectly.
- Prediction Confidence — Measures the model’s confidence in its predictions.
10. Final Results
The final production candidate achieved:
- 98.15% Test Accuracy
- 95.64% Macro Precision
- 98.67% Macro Recall
- 97.03% Macro F1-Score
- 98.16% Weighted F1-Score
- 1.85% Test Error Rate
- 212 Correct Predictions
- 4 Incorrect Predictions
The model successfully classified all 100 Early Blight test images and all 16 Healthy test images correctly. Four Late Blight images were incorrectly classified.
11. Conclusion
The Potato Disease Classification System successfully demonstrates the use of deep learning and transfer learning for automated potato leaf disease classification.
Using EfficientNetB0, transfer learning, fine-tuning, data augmentation, class weighting, and systematic evaluation, the final model achieved 98.15% accuracy on 216 unseen test images.
The strong precision, recall, and F1-score results indicate that the model can effectively distinguish between Early Blight, Late Blight, and Healthy potato leaf images within the evaluated dataset.
The project provides a complete end-to-end machine learning workflow and can serve as a foundation for an interactive image-based potato disease prediction application.
Note: This system is intended for educational, research, and demonstration purposes and should not be treated as a substitute for professional agricultural diagnosis.